
Link · hamel.dev ↗
How To Use Decision Models for Evals
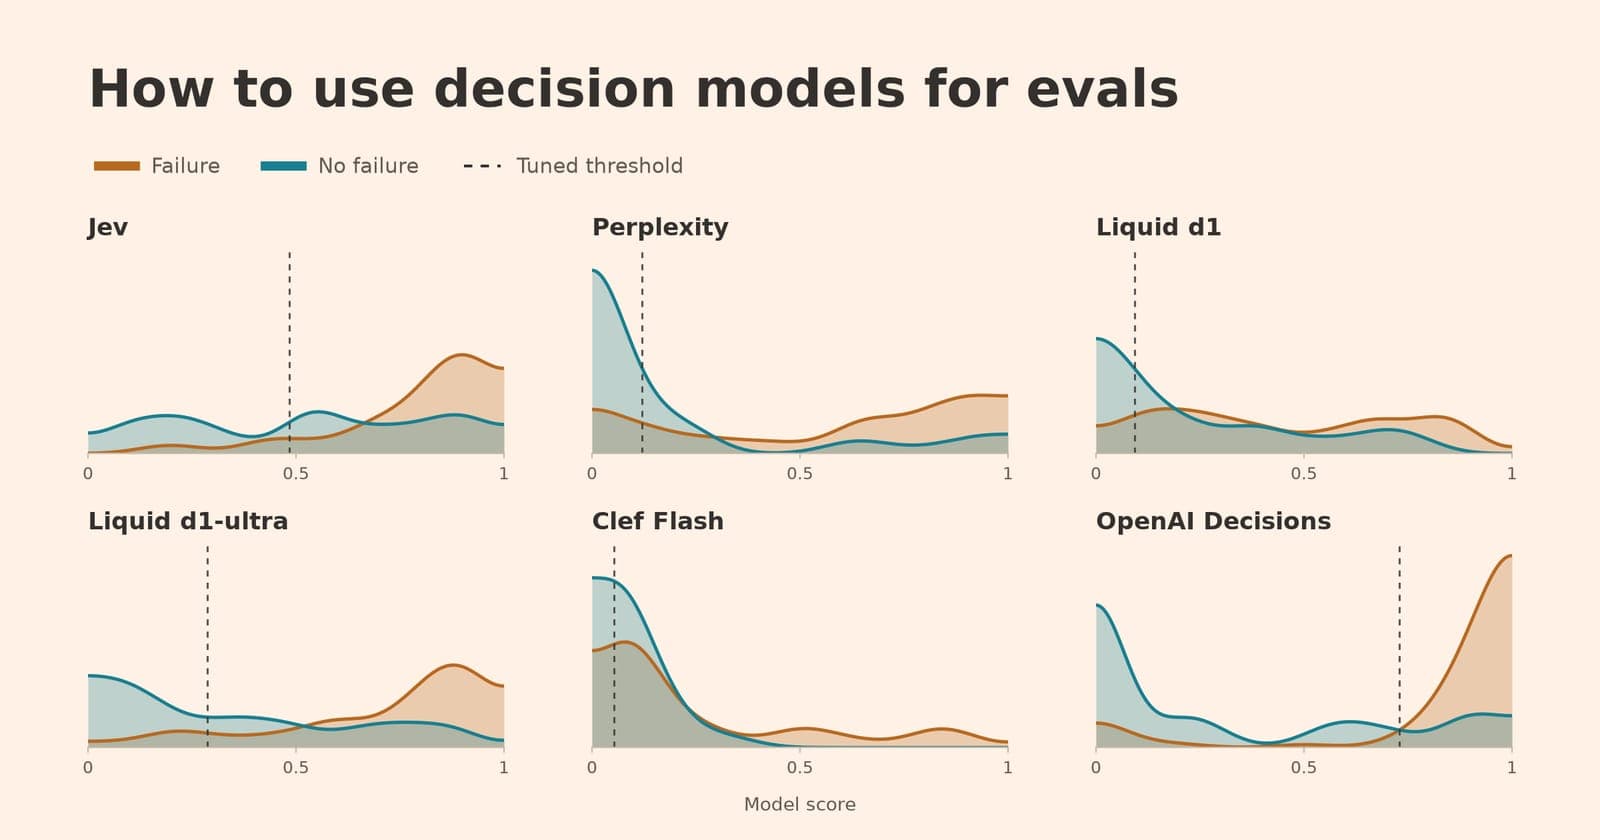
Husain and Antaripa Saha scored 98 labeled traces from an apartment-leasing assistant, looking for failed bookings and missed handoffs to a human, with six decision models instead of an LLM judge. The default 0.50 threshold often went untuned and wasted performance; tuned for F1 under an 80% floor on precision and recall with five-fold cross-validation, OpenAI's reached 0.87 at about 3.72 cents per 100 runs and Perplexity's 0.79 at about 0.82 cents. Calibration mattered as much as accuracy: for one group of traces, Clef Flash predicted an 8% failure rate where 60% had failed. If you swap a judge for something cheaper, tune and calibrate its threshold on your own labels before you trust the number.
Comments
Loading comments…